TL;DR
A November 22, 2026, Thorsten Meyer AI explainer maps how modern AI accelerators combine compute dies, stacked high-bandwidth memory and silicon packaging. Vendor specifications show rising memory bandwidth and larger package designs, while SK hynix says memory demand is expected to exceed supply through 2030. The article does not quantify how many accelerators packaging capacity can support or when supply will catch up.
Thorsten Meyer AI published a 3D explainer on November 22, 2026, showing how AI accelerators combine compute dies, stacked high-bandwidth memory (HBM) and silicon interposers inside one package. The report argues that memory bandwidth and advanced packaging, alongside compute, shape how quickly accelerators can serve AI workloads and how many packages manufacturers can supply.

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
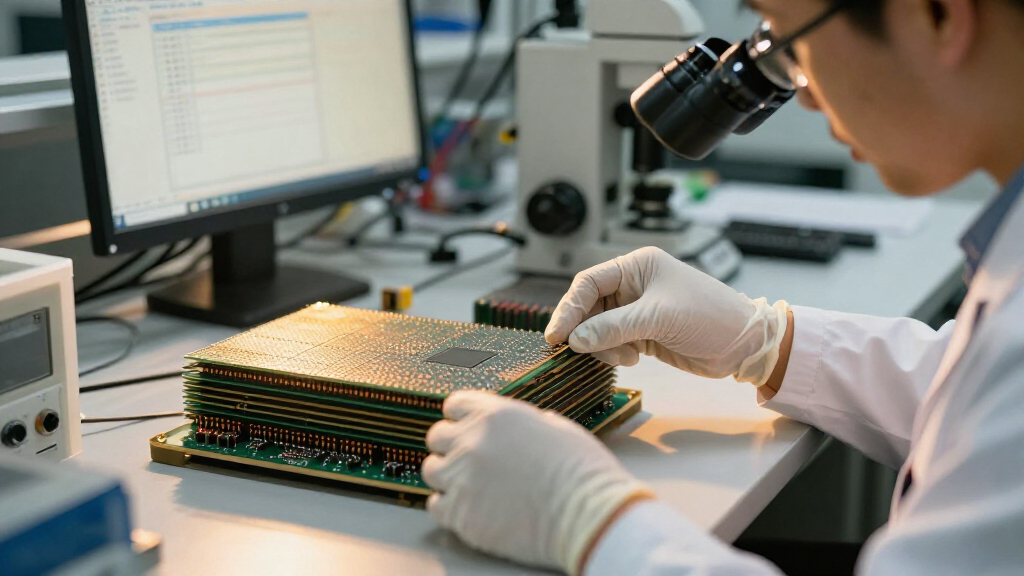
The explainer describes an accelerator as a layered assembly rather than a single chip. A package substrate provides connections to the surrounding module; a silicon interposer carries dense wiring between compute dies and memory; and a cold plate sits above the package for cooling. The accompanying 3D model follows documented layer order and component counts, while its dimensions are schematic because the cited vendors do not publish complete package measurements.
High-bandwidth memory sits close to the compute dies in vertical stacks. The DRAM layers connect through through-silicon vias (TSVs), which carry signals vertically through the chips. The article cites SK hynix describing TSVs as electrodes passing through fine holes in DRAM, and reports that its 12-layer product uses chips at the same overall thickness as an earlier eight-layer product. Samsung says its 12-high HBM3E achieved a seven-micrometer gap between chips.
Package and die configurations differ by product. NVIDIA says its Rubin GPU has two reticle-limited compute dies and 336 billion transistors. AMD’s CDNA 4 white paper describes the MI350 Series as eight vertically stacked accelerator complex dies and two I/O dies; the MI355X has 185 billion transistors and eight 12-high HBM stacks. AMD says its next-generation MI450X and MI455X use CoWoS-L packaging and stacked 3D hybrid-bonded compute dies.

Memory Bandwidth Shapes Accelerator Output
The design matters because compute units need a steady flow of data. HBM places memory close to the processor and connects it with many short, dense paths through the interposer. NVIDIA’s product figures cited by the explainer put memory bandwidth at 900 GB/s for V100 and 19.2 TB/s for Rubin. Those figures show the change across the named products; they do not by themselves establish how a particular model or workload will perform.
Packaging also affects how large and complex an accelerator can be assembled. TSMC says its CoWoS-S process can support a silicon interposer up to about 2,700 square millimeters, or 3.3 times a reticle area. For larger packages, CoWoS-L joins silicon bridges within a carrier layer. The explainer reports that TSMC CEO C.C. Wei said on October 15, 2026, that the company was in “real world production of 5x reticle size” and working on 9x and 14x designs.
For buyers, the implication is that accelerator availability depends on several linked production stages: compute dies, HBM and advanced packaging. SK hynix expects demand to exceed memory supply “through 2030,” according to the explainer. That is a company forecast, not a confirmed schedule for shortages or a measure of how many systems will be affected. Persistent constraints could limit the number of systems vendors can deliver and put pressure on prices, but the source gives no price forecast.
Products Worth Considering

Bose QuietComfort Ultra Wireless Noise-Cancelling Over-Ear Headphones with Spatial Audio, White Smoke

Jackery Explorer 300 Portable Power Station, 292Wh

Apple Watch Series 12 GPS 42mm Smartwatch
As an affiliate, we earn on qualifying purchases.
From Package to Rack
The explainer follows the hardware from individual memory layers to a complete rack. In its AMD example, an accelerator module uses an OCP Accelerator Module form factor; eight modules fit on a universal baseboard, with AMD’s Infinity Fabric connecting them. At rack scale, the article uses NVIDIA’s DGX GB user guide for system counts and an Open Compute Project listing for the rack outline. Its graphic sizes remain schematic.
The packaging terms describe different parts of that assembly. HBM is stacked DRAM; TSVs connect layers within each stack. A silicon interposer connects memory and logic dies across the package, while CoWoS refers to TSMC’s chip-on-wafer-on-substrate packaging family. A reticle is the maximum area printed in a single exposure by a lithography scanner, which makes reticle limits relevant when designers want to combine large dies and memory in one package.
Industry specifications and products have also moved toward taller memory stacks. The article cites JEDEC’s April 2025 HBM4 standard, which permits four-, eight-, 12- and 16-high stacks and up to 64 GB per stack. Such standards describe supported configurations; they do not mean every listed stack height or capacity is shipping in a given accelerator.
““large silicon interposer area to accommodate various functional top dies, including logic chiplets, with high-bandwidth memory (HBM) cubes stacked over it””
— TSMC, describing CoWoS-S
Capacity and Costs Remain Unspecified
The cited material does not give package dimensions in millimeters, complete production volumes, customer delivery schedules or a price outlook. The 3D model’s sizes are schematic, so it should not be read as a scale drawing. The source also does not quantify how much of accelerator availability is attributable to HBM, packaging capacity or other production limits.
Vendor specifications describe product designs, while supply forecasts are company statements. The article does not provide independent measurements comparing real-world performance across the named accelerators, nor does it establish that higher bandwidth alone determines model response time. The extent and duration of any shortages, and their effect on buyers, remain uncertain.
Watch HBM and Package Output
The next indicators are product and manufacturing updates: whether vendors ship the described HBM4 configurations, how quickly TSMC expands large-package production, and whether memory supply meets the demand forecast. Buyers can also watch announced accelerator availability and system pricing for evidence of how those constraints reach the market. The explainer names no specific delivery date or upcoming milestone, so the timing of any change remains open.
Key Questions
What does HBM mean in an AI accelerator?
HBM means high-bandwidth memory: DRAM chips stacked above a base die and connected vertically using through-silicon vias. The stacks sit close to compute dies to provide dense memory connections.
What does a silicon interposer do?
A silicon interposer carries dense wiring between compute dies and HBM stacks inside a package. TSMC’s CoWoS family includes packaging approaches for assembling those components.
How many HBM stacks does the MI355X use?
AMD’s CDNA 4 white paper, as cited by the explainer, lists eight 12-high HBM stacks for the MI355X.
Does the source confirm an AI chip shortage through 2030?
No. It reports SK hynix’s forecast that memory demand will exceed supply through 2030. That forecast does not specify the size of a shortfall or establish how it will affect accelerator shipments.
Source: Thorsten Meyer AI