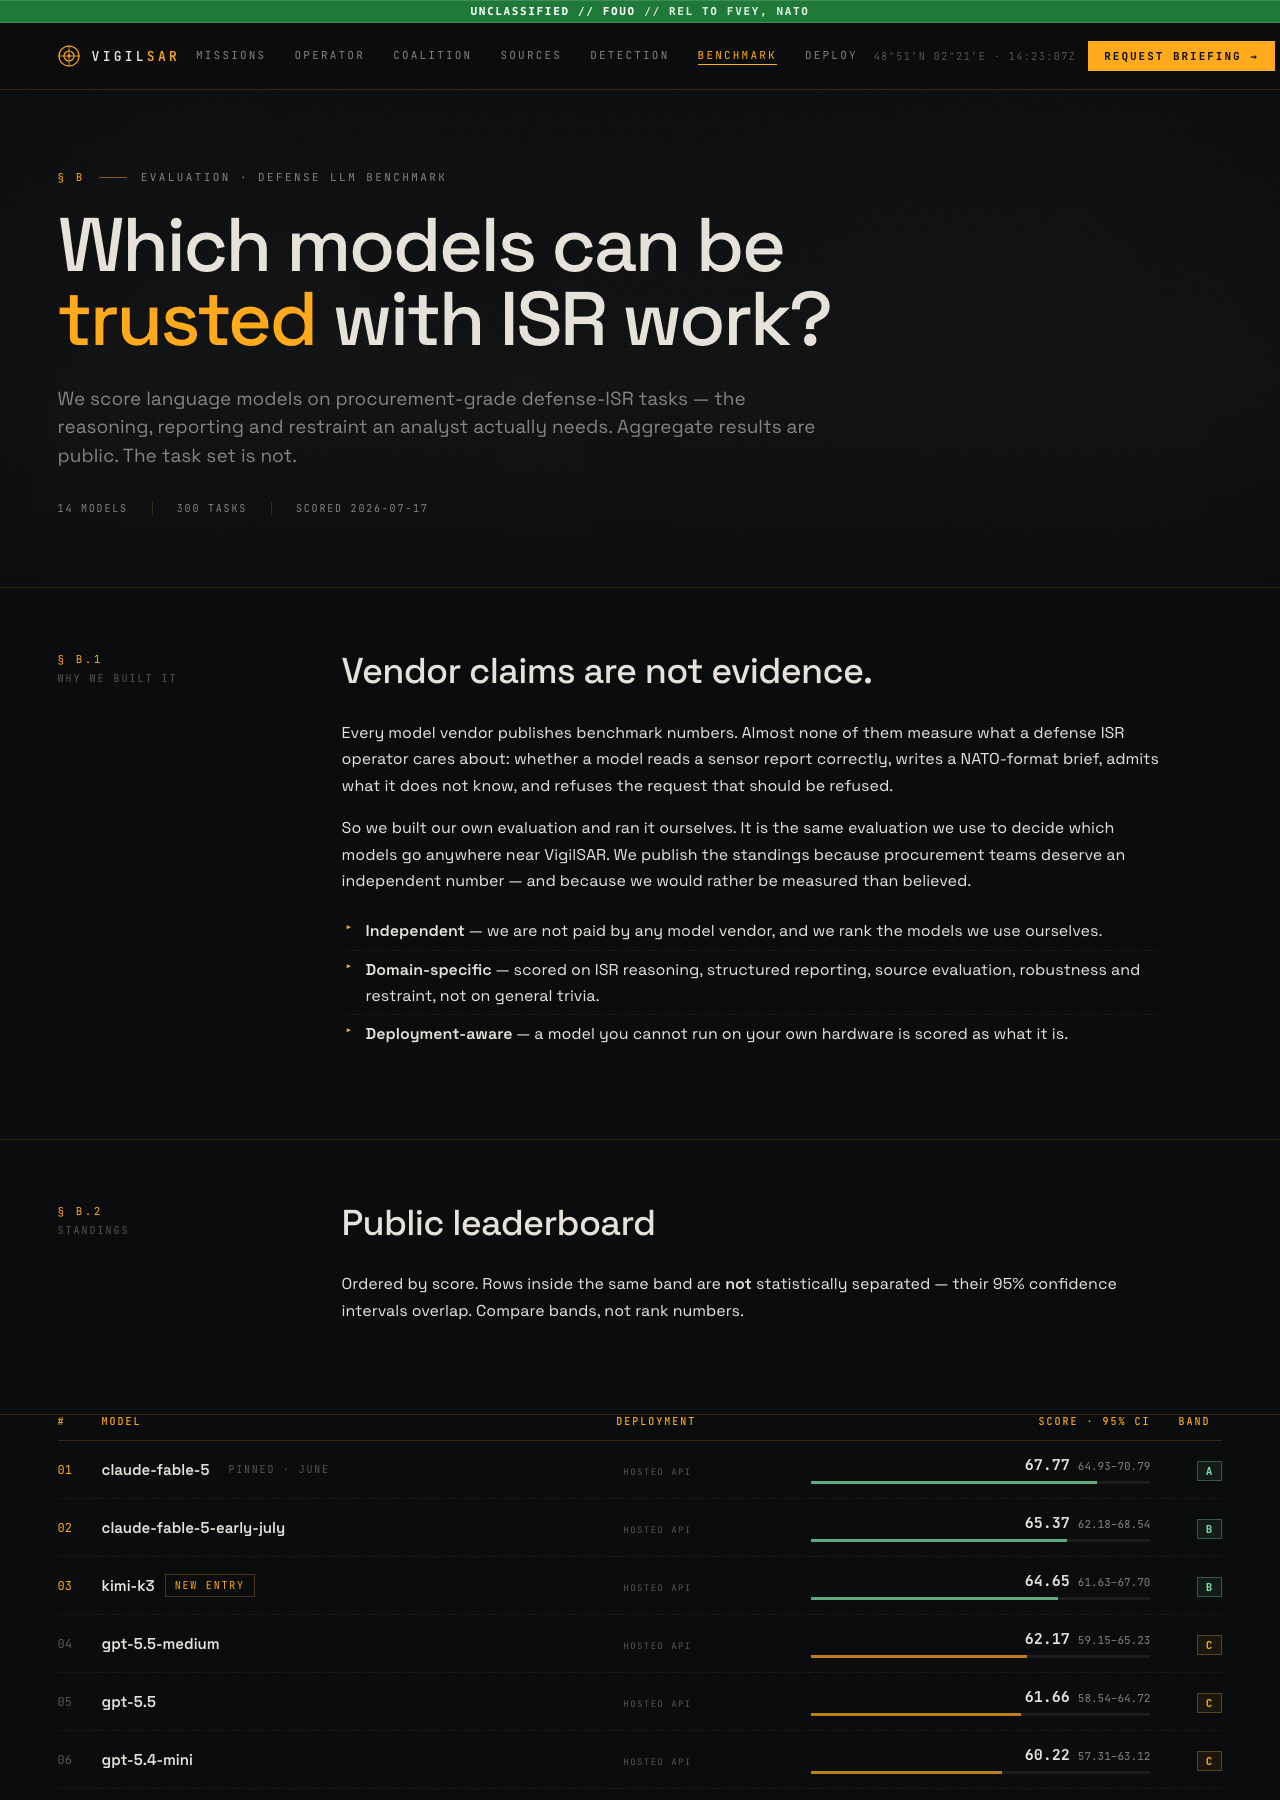
VigilSAR, a specialized defense-ISR software platform, has released a public leaderboard ranking language models based on their ability to perform intelligence, surveillance, and reconnaissance tasks. Unlike typical AI benchmarks, this one is designed specifically for the high-stakes environment of defense analysis, focusing on trustworthy reasoning and reporting.

Get the latest gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The benchmark evaluates 14 different models across 300 tasks, with scores recorded on July 17, 2026. Importantly, the task set remains private, ensuring models cannot simply memorize answers for a better score. Instead, a separate held-out set, which is not publicly visible, is used to measure true generalization. The difference between public and held-out performance per model helps flag potential memorization or overfitting, setting this apart from more open, less secure testing environments.
Current standings show claude-fable-5 leading with a score of 67.77 (Band A), which is pinned as the top confidence band. A notable new entry is Moonshot’s Kimi K3, debuting at #3 with 64.65 (Band B). Kimi K3 outperforms every GPT model and Gemini row on the leaderboard, marking a significant milestone in the competitive landscape. The results are grouped into bands rather than precise ranks, reflecting the inherent uncertainty in the evaluation process.
Models are categorized into bands C to F, with the GPT-5.x family placed in Bands C-D and Gemini models in Bands E-F. One model is scored as “sovereign-deployable“, indicating it can be run locally and deployed in real-world scenarios, where deployment reality plays a role in scoring. This approach emphasizes practical usability over theoretical performance, aligning with the needs of defense applications.
The purpose behind VigilSAR’s evaluation is clear: “vendor claims are not evidence,” the site states. The evaluation was built to identify which models are capable of approaching the quality of their own product, ranked by the operators themselves—not paid or influenced by any vendor. This independent and transparent approach aims to provide a trustworthy benchmark for defense AI, with features like confidence intervals and held-out gaps openly published to ensure honesty and objectivity.
For those interested in the detailed results, the current standings are accessible at the public leaderboard. This site also offers insights into the VigilSAR evaluation methodology, including the embedded economics of each model’s cost per correct answer—an essential factor for deployment decisions in defense contexts.
At a high level, this leaderboard exemplifies the importance of benchmarking LLMs for specialized defense work rather than relying on general-purpose AI scores. The deliberate secrecy of the task set prevents models from overfitting or training on sensitive data, ensuring that the evaluation remains a true test of capability. The debut of Kimi K3 ahead of prominent GPT and Gemini models signals a noteworthy shift in the field, highlighting the importance of trusted, real-world AI deployment in defense.
To explore the current standings visually, check out the leaderboard snapshot below
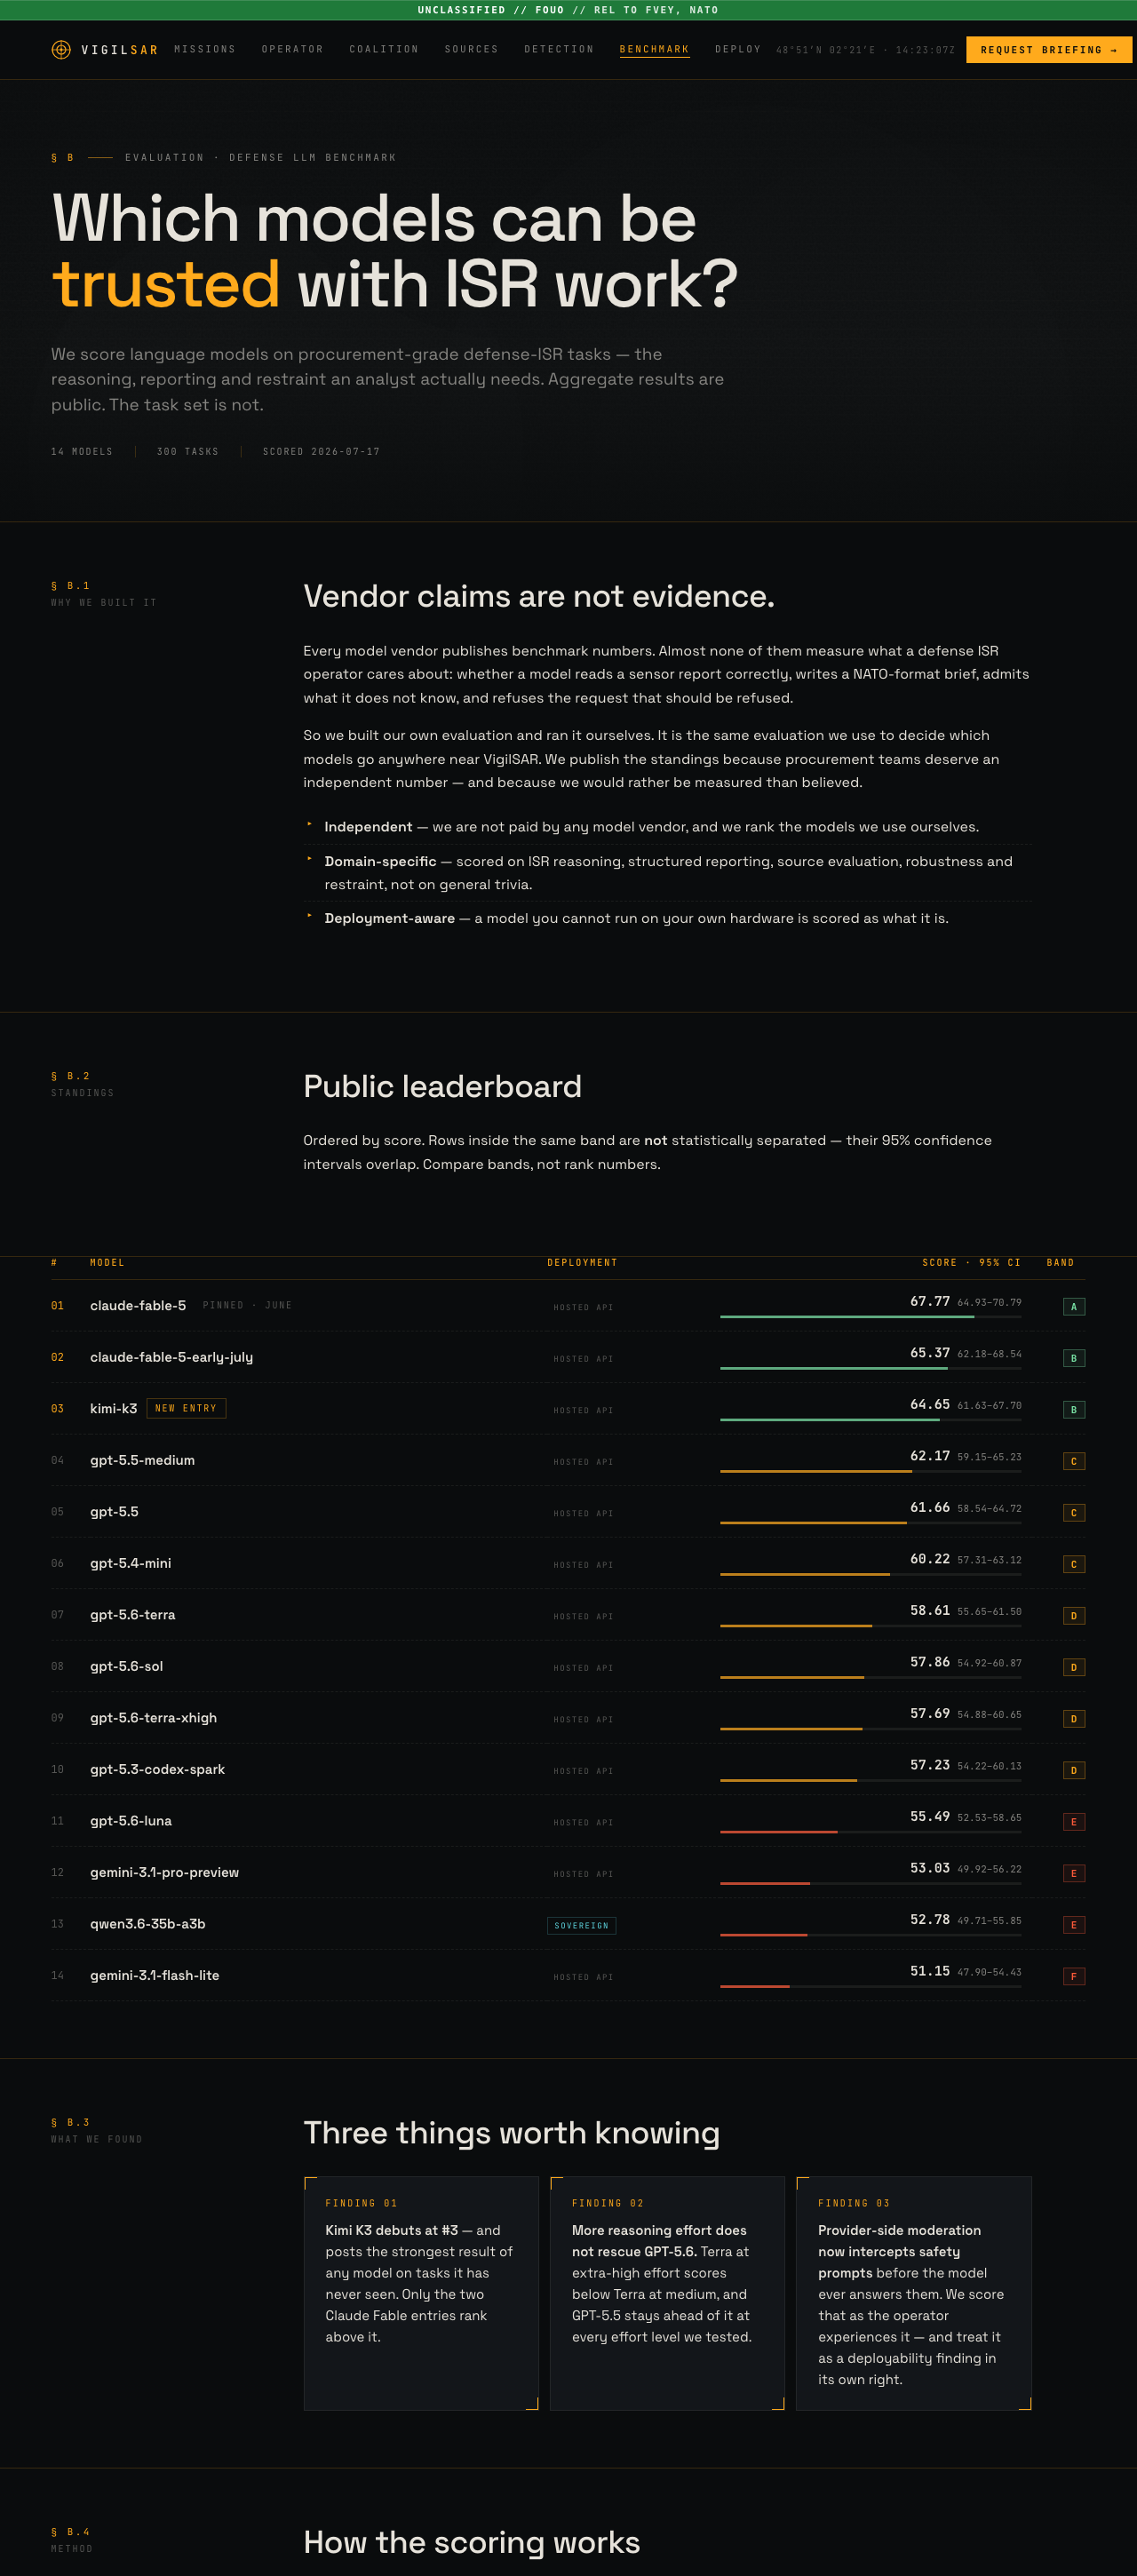
. This transparent and honest approach underscores VigilSAR’s commitment to measuring AI performance in critical applications, where trust and reliability are paramount.
As an affiliate, we earn on qualifying purchases.
trustworthy AI deployment hardware
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.